Scraping Tools
Scraping tools are important for building certain types of directories. In this section, you'll find the data aggregation and scraping tools to complete any directory project.
Scrapy | The Scraper With No Pricing Page
A BSD-licensed Python scraping framework with 64,000 GitHub stars and no metering of any kind. The tool you reach for when the per-row bills stop making sense.
Bright Data | Pre-Built Scrapers That Only Charge for Success
A library of ready-made scrapers including Google Maps, LinkedIn and Crunchbase, billed per delivered record with nothing charged for failures. The free tier gives 5,000 records a month.
PhantomBuster | Social Scraping for Directories Built From People
Cloud automations that pull profile and engagement data from LinkedIn, X, Instagram and 15+ other platforms. Ships an MCP server, so Claude can run your scrapes directly. From 56 euros a month.
ScraperAPI | The Unblocking Layer for a Scraper You Built Yourself
Send it a URL, get back the HTML that would otherwise be blocked. Proxy rotation, JS rendering and CAPTCHA handling behind one API call. From $49 a month, with a 7-day trial and 5,000 credits.
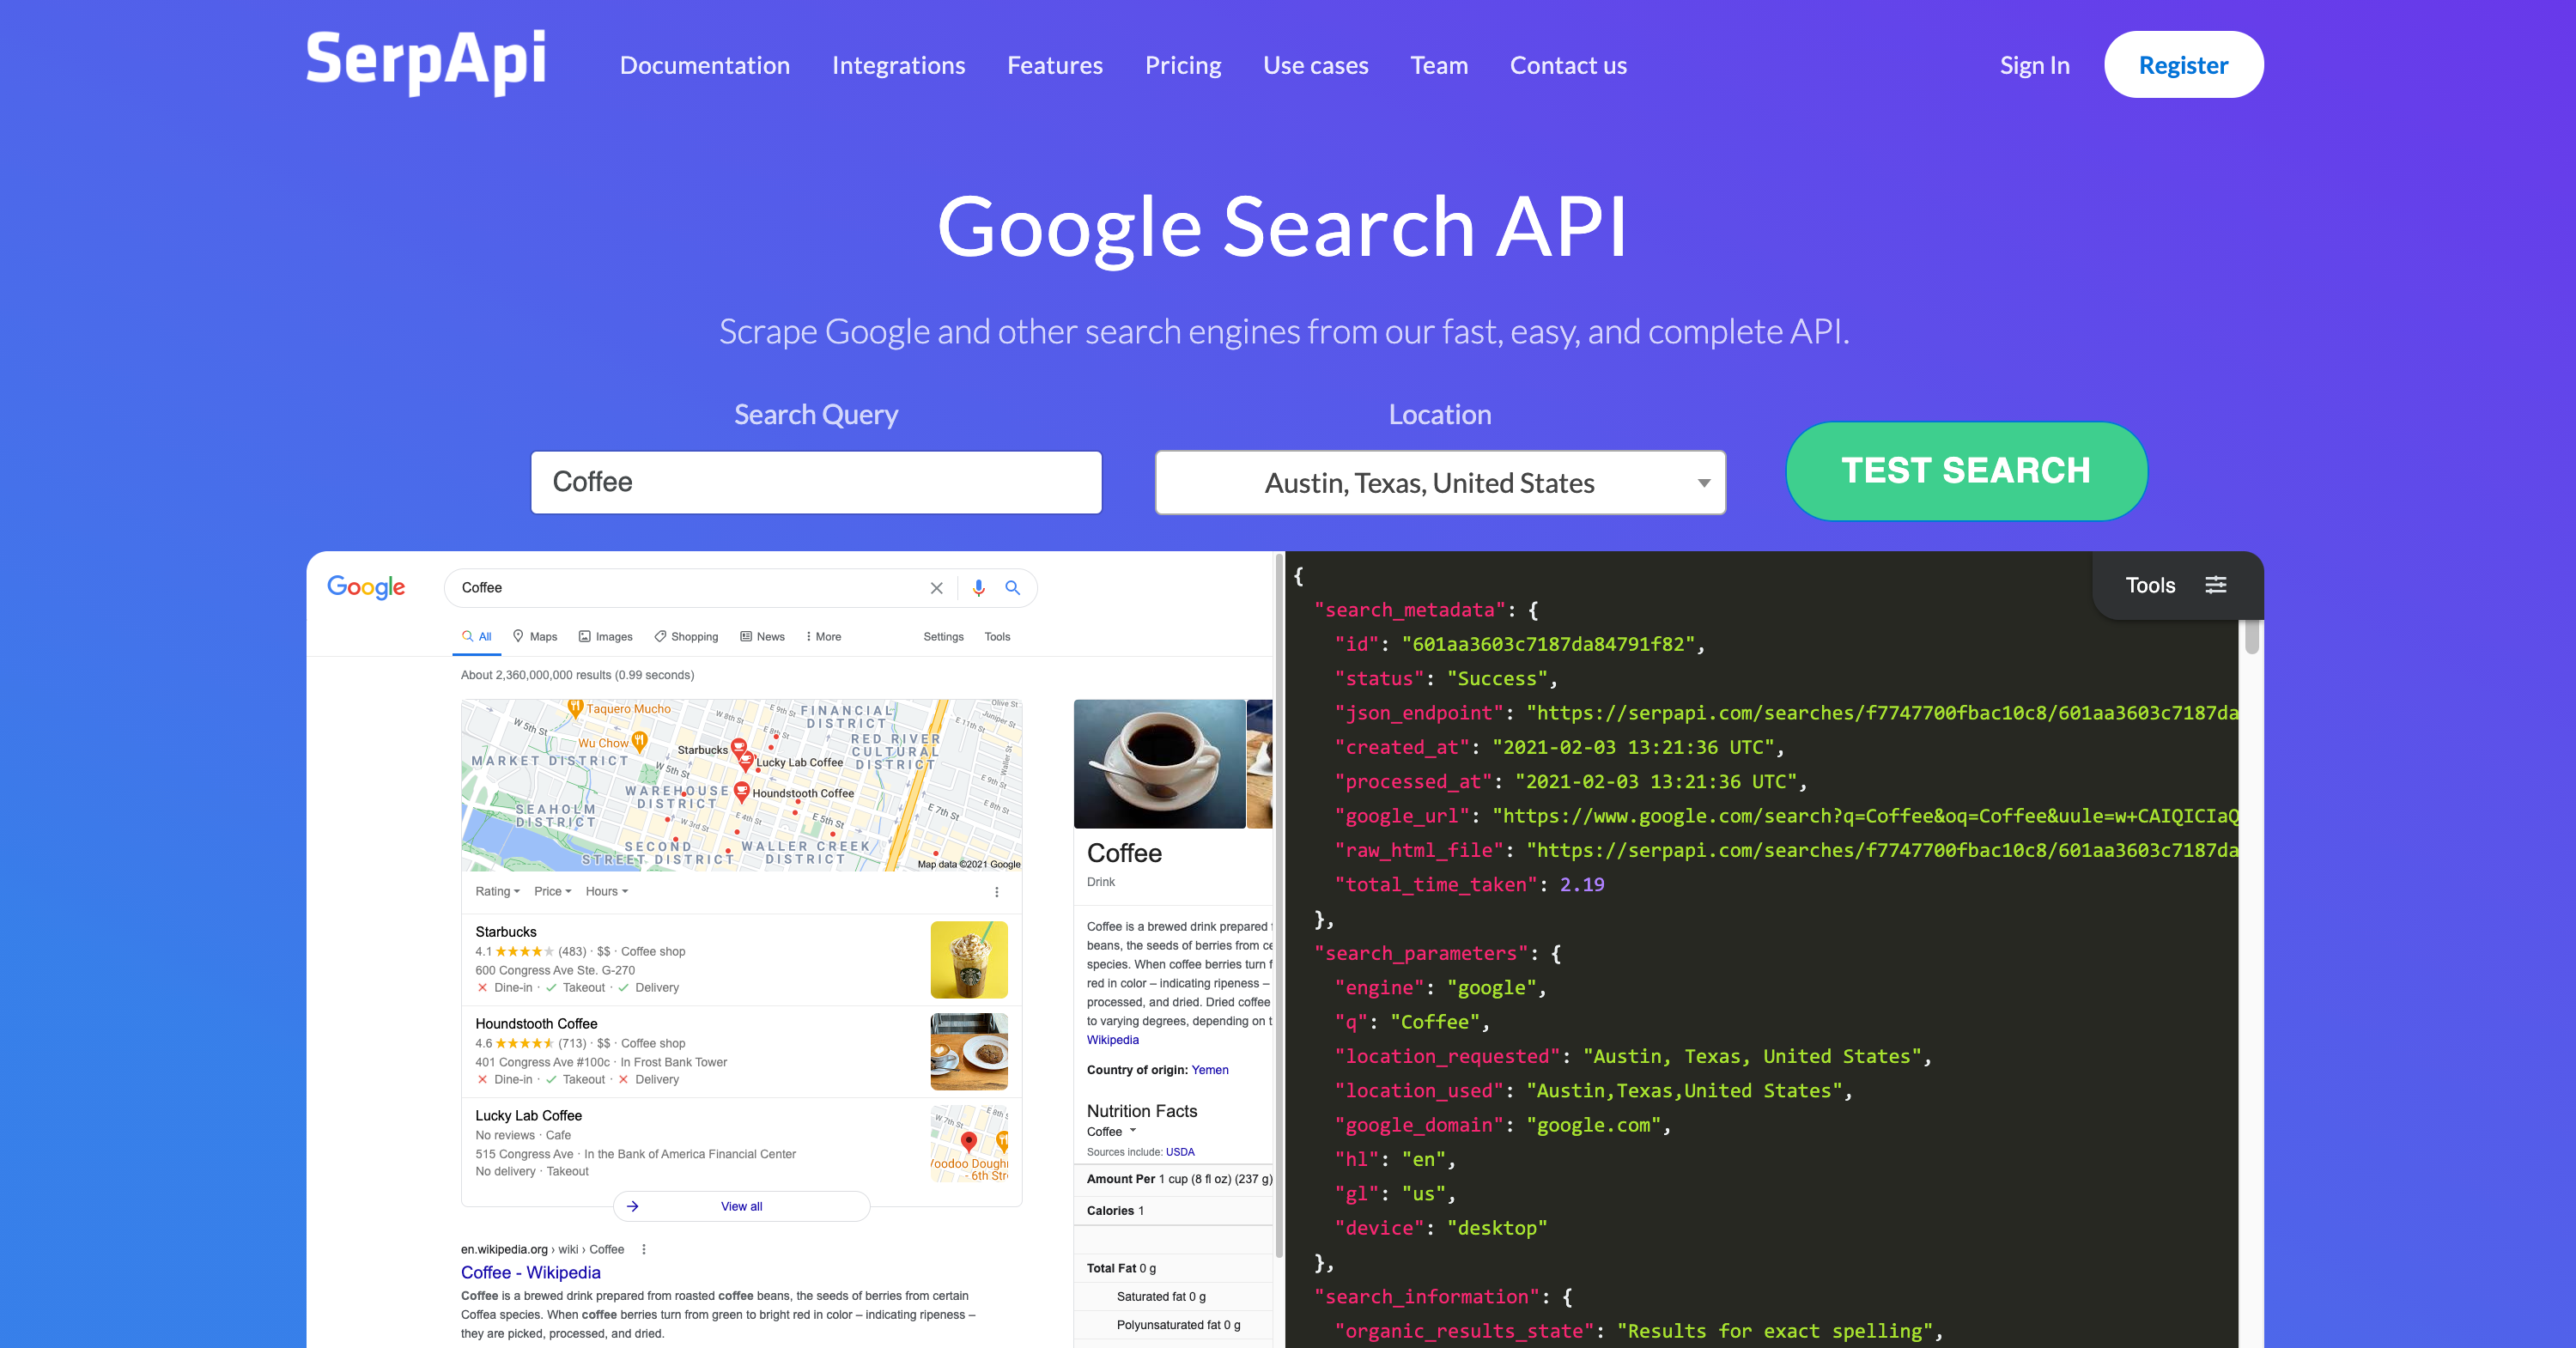
SerpApi | Google Maps and Search Results as Structured JSON
An API that returns Google Maps places and search results as clean JSON, with place_id, coordinates, hours, ratings and phone numbers. Paid plans include a legal shield. Free tier gives 250 searches a month.
Instant Data Scraper | Free Chrome Extension for Validating a Niche
A free Chrome extension that guesses the list structure on any page and exports it to CSV or Excel. No account, no credits, no configuration. The fastest way to find out whether your niche has data.
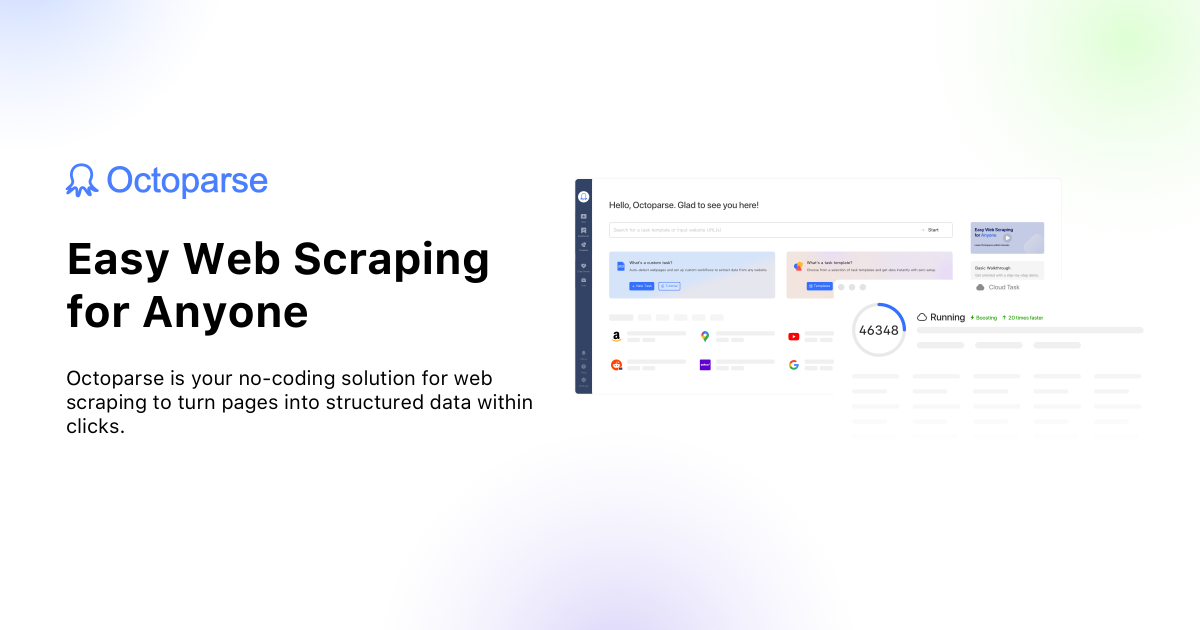
Octoparse | Visual Desktop Scraper With 50,000 Free Rows a Month
A point-and-click desktop scraper whose free plan exports up to 50,000 rows a month across 10 tasks. Paid plans move extraction to the cloud with IP rotation and CAPTCHA solving.
Browse AI | No-Code Scraping Robots That Keep a Directory Fresh
Train a scraping robot by recording your screen, then schedule it to re-run and flag what changed. The free plan gives 50 credits a month, and one credit pulls 10 rows.
Apify | Ready-Made Scrapers for Filling a Directory
A marketplace of thousands of pre-built scrapers, including a Google Maps scraper that returns business name, address, phone, website, hours and ratings from $1.50 per 1,000 places.
Google Maps Data Scraper
Scrape Google Maps data in seconds. Outscraper’s Google Maps Scraper lets you extract business names, emails, phone numbers, reviews & ratings. No-code or API. Try free.

Firecrawl - The Web Data API for AI
The web crawling, scraping, and search API for AI. Built for scale. Firecrawl delivers the entire internet to AI agents and builders. Clean, structured, and ready to reason with.
Lead Scrape | Local Leads Scraper Software
Find new business leads. Lead Scrape helps you find B2B companies in any industry and supports over 50 countries. Free Trial Available for Windows & Mac OS.
The Empty Room Problem
You have a directory idea. It’s good. You bought the domain. You installed the theme.
Now you have a problem. A big one.
Your site is empty.
Nobody visits an empty directory. Nobody pays for a listing on an empty directory. It is a ghost town. You need data. You need listings. You need them yesterday.
You have two choices.
Choice one: You type. You search Google. You copy. You paste. You repeat. You do this five hundred times. Your eyes bleed. You hate your life. You quit before you launch.
Choice two: You scrape.
I prefer choice two.
Scraping is the cheat code for directory builders. It is how you go from zero listings to a thousand listings in an afternoon. It is how you validate your idea before you waste months on it.
This is not about being a hacker. It is about being efficient.
Most solopreneurs get this wrong. They think content creation means writing unique blog posts. For a directory, content is data. Structured data. Names. Addresses. Phone numbers. Reviews. Images.
You cannot hand-craft this at scale. You are one person. The internet is big.
You need robots.
How to Think About Scraping
Stop thinking of scraping as "stealing."
If you take someone’s blog post and put it on your site, that is theft. If you take public facts—business names, locations, hours of operation—that is aggregation.
Google scrapes. Bing scrapes. The biggest travel sites scrape. The entire AI industry is built on scraping.
You are an aggregator. You find scattered data. You clean it. You organize it. You present it in a way that is useful. That is the value you provide.
The data itself is a commodity. The organization is the product.
When you scrape, you are mining raw material. It comes out dirty. It has weird characters. The phone numbers are formatted wrong. The images are low resolution.
Your job is not just to scrape. It is to refine.
A scraper is just a tool. It is a hammer. You can use it to build a house. You can use it to smash your thumb.
Why You Need These Tools
Speed.
That is the only reason that matters.
I built a directory for local coffee shops once. I tried to do it manually. I estimated it would take me 15 minutes per listing to find the shop, get the photos, write the description, and find the social links.
To get 100 listings? 25 hours. Three full work days.
With a scraper? I set it up in 20 minutes. I ran it. I had 500 listings in a CSV file while I ate lunch.
That is the difference.
Validation is another reason.
Maybe your directory idea is bad. Maybe nobody wants a directory of "Pet-Friendly Yoga Studios."
If you spend three weeks manually adding listings to find that out, you lost three weeks.
If you scrape the data and launch in one day, you lost one day.
Fail fast. Scraping helps you fail fast.
The Mechanics (Without the Code)
You might be scared. You see "Python" or "API" or "Selector" and you want to run away.
Don't.
You do not need to be a developer to scrape. You just need to understand how a website works.
Every website is just a text file. It is HTML. It looks like a mess, but it has structure.
A title is usually inside a tag like <h1>. A price is usually inside a tag with a class like .price.
A scraper is a robot that reads the text file. You tell it: "Go to this page. Find the text inside .price. Save it to a spreadsheet."
That is it.
The Three Levels of Scraping
Level 1: Browser Extensions
This is for beginners. You install a Chrome extension. You go to a website. You click a button. The extension guesses what the data is. You download a CSV. Tools: Instant Data Scraper, Web Scraper. Best for: Simple sites. One-off jobs. Small amounts of data.
Level 2: No-Code Cloud Tools
You pay a monthly fee. You point and click to build a "robot." The robot runs on their servers, not your laptop. You can schedule it to run every week. Tools: Browse AI, Octoparse. Best for: Recurring jobs. Sites that need a login. People who value their time.
Level 3: Custom Scripts / APIs
You write code or hire someone to write code. You use Python libraries. You use headless browsers. Best for: massive scale. Complex sites. Beating anti-bot protections.
For your first directory, stay at Level 1 or Level 2.
The Workflow
Here is exactly how I would do it.
1. Pick Your Source
Where is the data right now? Is it on Google Maps? Yelp? Yellow Pages? A niche industry association website? Pick one source. Don't try to combine five sources yet. That is a nightmare for later.
2. Map Your Fields
What does your directory need?
- Business Name
- Address
- Website URL
- Phone Number
- Category
- Image URL
Do not scrape things you do not need. It clutters your database.
3. The Scrape
Use your tool. If you are scraping a paginated list (Page 1, Page 2, Page 3), make sure your scraper knows how to click "Next." Run a test. Scrape 10 records. Check the data. Did you get the email address? Or did you get a "mailto:" link text? Fix it. Run the full scrape.
4. The Clean Up
This is the part nobody talks about. Raw scraped data is ugly.
- The names might be in ALL CAPS.
- The addresses might have extra spaces.
- The websites might be missing "https://".
Use Google Sheets or Excel. Use "Find and Replace." Use "Trim." Use "Proper Case." If you import dirty data, your directory looks like spam. If your directory looks like spam, you fail. Spend 80% of your time cleaning.
5. The Import
Most directory themes have a CSV importer. Map your columns. Name -> Title. Address -> Location. Run it.
Boom. You have a directory.
Tools You Might Use
I won't list every tool. There are hundreds. I will list categories.
The "I have $0" Category
- Google Sheets: Yes, you can scrape with Google Sheets. Look up
IMPORTXML. It breaks often. It is slow. But it is free. - Instant Data Scraper: A chrome extension. It uses AI to guess what part of the page is the list. It works surprisingly well on simple tables.
The "I have a budget" Category
- Apify: This is a marketplace of scrapers. You don't build the scraper. You rent one. Someone else already built a "Google Maps Scraper." You just pay $5/month to use it. This is usually the best option for directory builders.
- Bright Data: Pre-built scrapers for Google Maps, LinkedIn and Crunchbase, with a permanent free tier of 5,000 records a month and no charge for failed scrapes. Good when you want clean, structured records rather than raw HTML.
The "I want to build it" Category
- Bardeen: An automation tool that runs in your browser. Very powerful. Connects to Notion or Airtable.
The Dark Side: Proxies and IPs
Websites do not like being scraped. If you send 1,000 requests in one minute to a small website, you look like an attacker. They will block your IP address.
Now you can't access the site. Neither can your scraper.
You need proxies. A proxy is a mask. It makes your request look like it is coming from somewhere else. If you scrape a lot, you need rotating proxies. Request 1 comes from Chicago. Request 2 comes from London. Request 3 comes from Tokyo.
Most paid tools (like Apify) handle this for you. Most desktop tools make you buy proxies separately. The exception is Leadscrape. It's desktop software, but it ships with its own rotating proxy pool. Nothing to buy, nothing to configure. If proxies make your eyes glaze over, start there.
Be nice. Do not hammer a small business website. Set a delay. Wait 2-5 seconds between requests. If you crash their server, you are the bad guy.
Pros of Scraping
Volume You can fill a specific niche in hours. "Dentists in Texas" is a big list. "Vintage Clothing Stores in Brooklyn" is a specific list. You can capture both easily.
Consistency Humans make typos. Robots do not. If the scraper is set up right, every phone number will be in the correct column. Every website link will work.
Updates Directories rot. Businesses close. They move. They change hours. If you rely on manual updates, your directory is dead in a year. If you scrape, you can re-run the scraper every month. You can update your listings automatically. This keeps your directory fresh.
Cons of Scraping
Structure Changes You build a scraper for Source X. It works perfectly. Next week, Source X changes their website design. They rename the "price" class to "cost." Your scraper breaks. You have to fix it. This happens all the time. Scraping is not "set it and forget it." It is high maintenance.
Dirty Data You will scrape garbage. You will scrape test listings. You will scrape businesses that closed three years ago but are still on the source site. You need a verification process. Maybe you email them all. Maybe you check if the website still loads.
Legal Risks We need to talk about this. Is scraping legal? Generally, yes. If the data is public. But websites can sue you. LinkedIn sued HiQ for scraping public profiles. The court battle went on for years. There are terms of service (ToS). Most sites say "No Scraping" in their ToS. If you violate ToS, they can ban you. They can send a cease and desist.
The Trap of Low Quality If you just scrape and publish, you add no value. Google knows that content exists elsewhere. It indexes the original source. It ignores your copy. You cannot just replicate. You must aggregate. Combine data from Source A and Source B. Add your own reviews. Add better filtering. If you are just a mirror, you are useless.
Real Examples
Let's look at real scenarios.
The Niche Job Board You want to build a job board for "Remote Rust Developers." You do not wait for companies to post jobs. You scrape "Rust" jobs from Indeed, LinkedIn, and StackOverflow. You filter them. You categorize them by salary. You launch with 50 jobs. Now you have traffic. Now companies will pay you to be at the top.
The Local Event Guide You want to list every live music event in your city. There are 20 venues. You write a script to scrape the calendar page of those 20 venues every Monday morning. You aggregate them into one list: "Live Music This Week." You save users from visiting 20 websites. You create value.
The Influencer Database You want a directory of "Micro-influencers in the Beauty Niche." You scrape Instagram or TikTok. You look for keywords in bios. You scrape follower counts. You calculate engagement rates. You sell access to this database to brands.
FAQ
Is scraping illegal? I am not a lawyer. This is not legal advice. In the US, scraping public data is generally considered legal (see hiQ Labs, Inc. v. LinkedIn Corp). However, scraping behind a login (where you agreed to terms) is riskier. Scraping personal data (names, emails) involves privacy laws like GDPR (Europe) and CCPA (California). Be careful with personal data. Business data is safer.
Will Google penalize my site? If you have "duplicate content," yes. If you scrape a Yelp description word-for-word, Google hates you. Scrape the facts (Name, Address, Phone). Write your own descriptions. Or use AI to rewrite them. Facts cannot be copyrighted. Creative text can be.
Do I need a developer? No. Tools like Browse AI or WebHarvy allow non-coders to scrape. However, if you want something very complex, hiring a freelancer on Upwork for $100 to write a script is often cheaper than buying a generic tool.
How do I get emails? Most sites do not list emails publicly to avoid spam. You usually scrape the website URL, then use a second tool (like Hunter.io or Snov.io) to find the email associated with that domain. This is a two-step process.
Can I scrape Google Maps? Google Maps is the holy grail of local data. It is hard to scrape directly. Google fights back. Use a specialized tool like Outscraper or Apify’s Google Maps Scraper. Do not try to write your own unless you are very bored.
What if I get blocked? It happens. Wait. Get a new IP address (VPN or Proxy). Slow down your scraper. If you are scraping too fast, you are attacking the site. Slow down.
Should I scrape images? Hosting images costs money and bandwidth. Hot-linking (using the image URL from the source site) is bad manners and often blocked. Download the image. Optimize it. Host it yourself. Check copyright. Just because an image is on the web doesn't mean you can use it. This is a high-risk area.
The Human Element
Scrapers are cold. Directories need warmth.
Use scraping to build the skeleton. You must add the meat. Reach out to the businesses you scraped. "Hey, I added you to my directory. Is this information correct?" This is your first marketing touchpoint. It turns a cold scrape into a warm relationship.
Many will say "Thanks, please change the photo." Great. Now they are engaged. Some will say "Remove me." Remove them. Immediately.
Do not be a jerk. If you respect the data and the people behind it, scraping is a superpower. If you spam and steal, you will fail.
Moving Forward
You have the idea. You know the tools exist.
The only thing stopping you is the friction of learning a new piece of software. Get over it. Spending four hours learning to use a scraper saves you four hundred hours of typing. That is the best ROI you will get this year.
Don't wait for listings to appear. Go get them.
Build your list. Launch your site. Start the business.